XSS in yarr
yarr is an open source RSS reader written in Go. I use it myself in my homelab and I was interested one day how yarr loads and renders this content.
Taking a look at their source we can see how. When you add an RSS feed, each post within the feed is treated as an "item" within yarr's object model. These are processed with the aptly named handleItem function.
func (s *Server) handleItem(w http.ResponseWriter, r *http.Request) {
	id, err := strconv.ParseInt(r.PathValue("id"), 10, 64)
        ...
	switch r.Method {
	case http.MethodGet:
		item := s.db(r).GetItem(id)
                ...
		item.Content = sanitizer.Sanitize(item.Link, item.Content)
		for i, link := range item.MediaLinks {
			item.MediaLinks[i].Description = sanitizer.Sanitize(item.Link, link.Description)
		}
                ...
When this loads the post from a remote url it first passes the content through the Sanitize function. This one is rather self explanatory.
// Sanitize returns safe HTML.
func Sanitize(baseURL, input string) string {
	tokenizer := html.NewTokenizer(bytes.NewBufferString(input))
	...
	attrNames, htmlAttributes := sanitizeAttributes(baseURL, tagName, token.Attr)
The sanitised content is returned in the "content" value of the response after it is serialised to JSON.
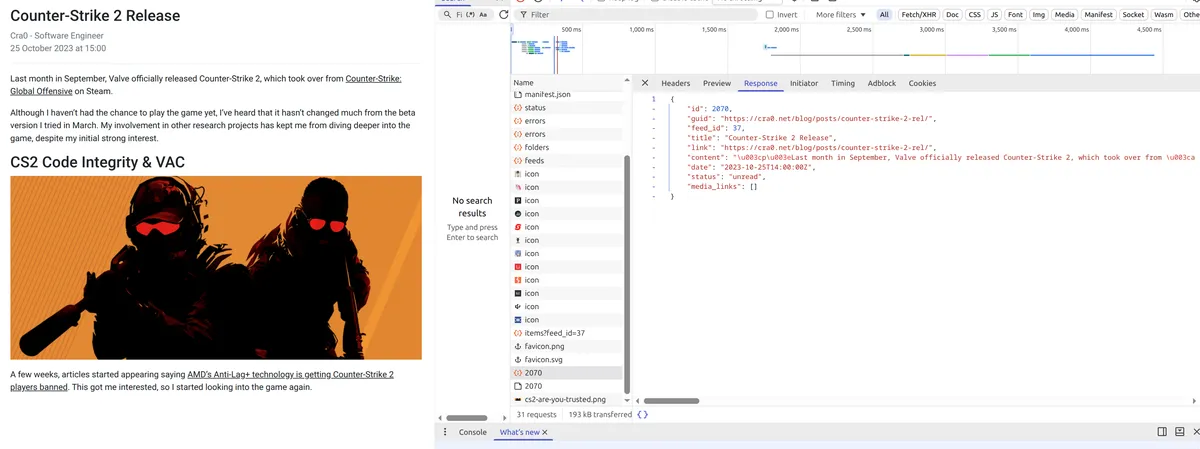 And from here dynamically rendered into the DOM.
With this model in mind, it was clear that if there was a gap in the sanitisation logic it would lead to XSS. So I took a closer look at how the function was implemented. This in itself is beyond explaining thoroughly for the purposes of this post as much of it is quite irrelevant to the vulnerability, so I will summarise it simply as recursive parsing of the HTML nodes sanitising from children first (in fact I'd say they are likely further flaws lurking here...). But onto the vulnerability in question, first we observe in getTagAllowList that iframe is an allowed tag, and src an allowed attribute.
 func getTagAllowList() map[string][]string {
     ...
     whitelist["iframe"] = []string{"width", "height", "frameborder", "src", "allowfullscreen"}
     return whitelist
 }
Furthermore in the function responsible for sanitising attributes we observe there is a special case for handling the src attribute of iFrames in isValidIframeSource:
func sanitizeAttributes(baseURL string, node *html.Node) []string {
	var attrNames []string
	var attrs []html.Attribute
	tagName := node.Data

	for _, attribute := range node.Attr {
		// attribute names are case-insensitive; the parser may preserve
		// the original casing, while the allowlist is lowercase.
		key := strings.ToLower(attribute.Key)
		value := attribute.Val

		if !isValidAttribute(tagName, key) {
			continue
		}

		if (tagName == "img" || tagName == "source") && key == "srcset" {
			value = sanitizeSrcsetAttr(baseURL, value)
		}

		if isExternalResourceAttribute(key) {
			if tagName == "iframe" {
				if isValidIframeSource(baseURL, attribute.Val) { // here!!!
					value = attribute.Val
				} else {
					continue
				}
			} else if tagName == "img" && key == "src" && isValidDataAttribute(attribute.Val) {
				value = attribute.Val
			} else {
				value = htmlutil.AbsoluteUrl(value, baseURL)
				if value == "" {
					continue
				}
				if !hasValidURIScheme(value) || isBlockedResource(value) {
					continue
				}
			}
		}
This function is as follows:
func isValidIframeSource(baseURL, src string) bool {
	whitelist := []string{
		"bandcamp.com",
		"cdn.embedly.com",
		"invidio.us",
		"player.bilibili.com",
		"player.vimeo.com",
		"soundcloud.com",
		"vk.com",
		"w.soundcloud.com",
		"www.dailymotion.com",
		"www.youtube-nocookie.com",
		"www.youtube.com",
	}

	domain := htmlutil.URLDomain(src)
	// allow iframe from same origin
	if htmlutil.URLDomain(baseURL) == domain {
		return true
	}
	return slices.Contains(whitelist, domain)
}


...


func URLDomain(val string) string {
	if u, err := url.Parse(val); err == nil {
		return u.Host
	}
	return val
}
tldr, it takes the provided URL (the one in the iFrame src), extracts the host part of the Url, checks it either matches the yarr base URL or an entry in the defined whitelist and rejects it if not.
The URL is parsed with net/url. The package descriptions states
Package url parses URLs and implements query escaping. See RFC 3986. This package generally follows RFC 3986, except where it deviates for compatibility reasons. RFC 6874 followed for IPv6 zone literals.
And with this comes the trick that enables the polyglot payload. In RFC 3986 the character sequence marks the beginning of the authority section (which contains the host accessed by URLDomain).
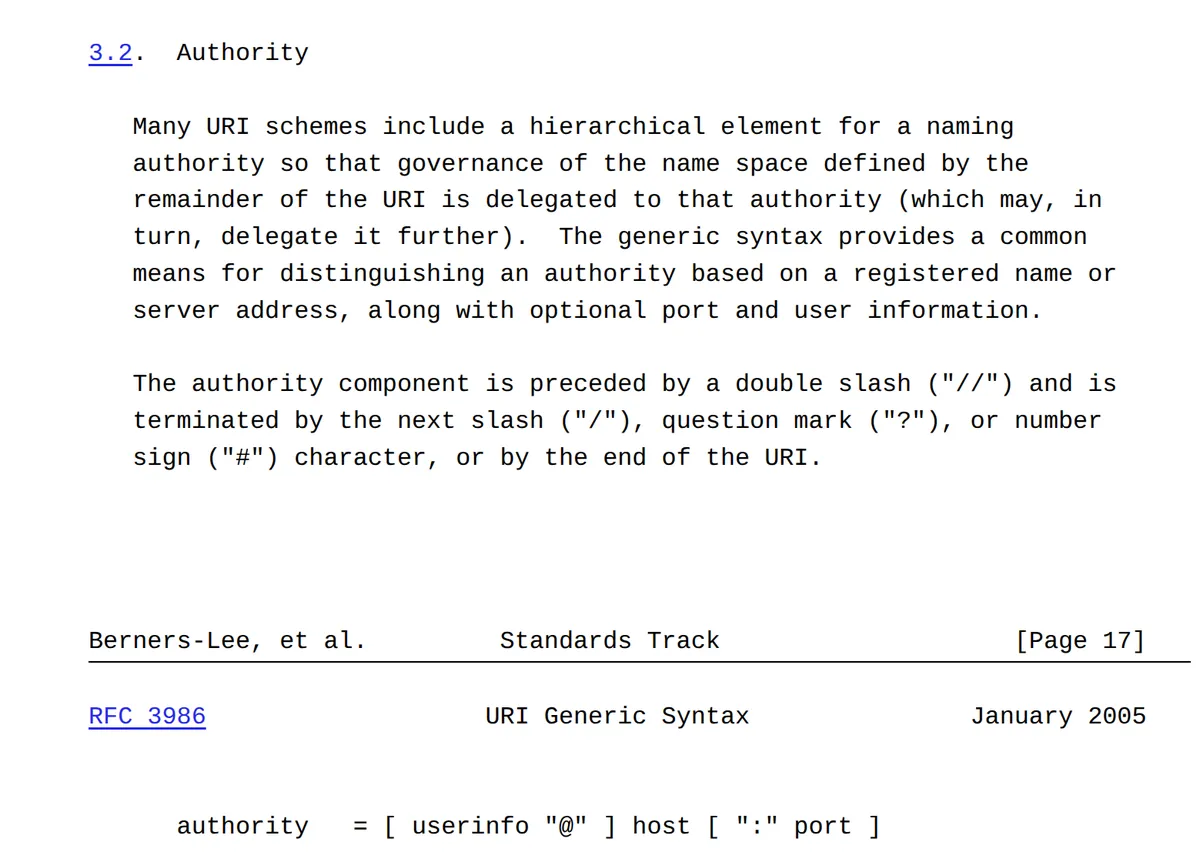
We combine this with the fact that iFrames will happily process javascript: URIs in their src to arrive at javascript://www.youtube.com/%0a<arbitrary-js>. net/url sees the authority www.youtube.com, extracts the host (here it is the entire authority) matches it to the whitelist and approves. Yet in the web browser, when this is processed as a javascript: URI everything after the colon is treated as JavaScript code (after a round of URL decoding). Therefore we arrive at:
<iframe src="javascript://www.youtube.com/%0a<arbitrary-js>"></iframe>
which is processed as
//www.youtube.com/
<arbitrary-js>
note '//' doubles as a JavaScript comment here (and %0a a newline on decoding) - a different meaning in each grammar.
The final piece is the permissive sandbox policy applied to iFrames by default
func extraAttributes(tagName string) ([]string, []html.Attribute) {
	switch tagName {
...
	case "iframe":
		return []string{"sandbox", "loading"}, []html.Attribute{
			{Key: "sandbox", Val: "allow-scripts allow-same-origin allow-popups"},
			{Key: "loading", Val: "lazy"},
		}
...
	default:
		return nil, nil
	}
}
Putting it all together, an RSS feed can XSS any yarr user who loads their post, here a simple demo (rewriting the parent DOM because no alerts with that policy (: )
I notified the maintainers of yarr about this finding but didn't get a response. With that said I don't see much immediate impact given yarr's account-less nature, at most spying on what other RSS feeds your subscribers are looking at. Nevertheless it was a fun little finding, thanks for reading.